I Built All 5 Web Rendering Strategies From Scratch. Here's What I Actually Learned
A from-first-principles case study on five web rendering strategies (Static Site Generation, Server-Side Rendering, Client-Side Rendering, Incremental Static Regeneration, and Partial Pre-Rendering), built with zero frameworks using Node.js's built-in http module.
I built five web rendering strategies from scratch using only Node.js's http module. SSG bakes HTML at build time, SSR renders per request, CSR sends an empty shell to the browser, ISR adds a staleness clock to SSG, and PPR combines build-time and request-time rendering on the same page. Each strategy decides when and where to call the same render function.
Updated October 15, 2026. I reviewed this post against the code and
found mistakes in both. The biggest correction is in the PPR section:
streaming a script after </html> works in every browser, but the HTML spec
treats it as a parse error, so I added a fourth attempt that holds back the
closing tags. I also fixed three ISR bugs that only showed up under tests and
load, added measured numbers, and added a streaming SSR route so you can
compare it with PPR yourself. The code changes are in the repo
history (opens in new tab).
I built four rendering strategies from scratch, in one project, sharing the same templates and data layer, using nothing but Node.js's built-in http module. Then a mock interview asked me about a fifth, and I built that too. No Next.js, no Express, nothing hiding what happens between the request and the response.
The thing I kept running into: the implementations are small. The concepts are not. And a few of the bugs I found only showed up once I put the server under load.
The full source is at github.com/atharvdange618/rendering-strategies (opens in new tab), and you can try every strategy live at rendering.atharvdange.com (opens in new tab).
The One Question Every Strategy Answers
Every rendering strategy answers one question:
Where and when does HTML get generated?
The performance characteristics, the SEO tradeoffs and the infrastructure you need all follow from that answer. Once you have it, the acronyms stop feeling like a grab bag and start to look like a set of deliberate choices.
                    WHO generates the HTML?
                           │
              ┌────────────┴────────────┐
              │                         │
           SERVER                    BROWSER
              │                         │
            WHEN?                      CSR
              │
    ┌─────────┴──────────┐
    │                    │
BUILD TIME          REQUEST TIME
    │                    │
   SSG                  SSR
    │
    + STALENESS WINDOW?
    │
   ISR
CSR moves HTML generation into the browser. SSG and SSR both generate on the server, at different times. ISR sits between them and uses staleness as the trigger for regeneration. PPR comes later, because it breaks this diagram.
The Project Architecture
The key decision was a shared template layer that every strategy calls into. One templates.js file, called at different times and from different places.
rendering-strategies/
├── data/
│   └── posts.json             ← single source of truth
├── dist/                      ← build output
│   ├── ssg.html
│   ├── isr.html               ← first ISR cache, regenerated by the server
│   └── ppr-shell.html
├── client/
│   └── app.js                 ← runs in the browser for CSR
└── src/
    ├── server.js              ← HTTP server and router
    ├── build.js               ← builds SSG, ISR and PPR output
    ├── templates.js           ← SHARED: renderPostList(), htmlShell()
    ├── isr-cache.js           ← ISR cache state + revalidation
    ├── trending.js            ← simulated request-time data (2s delay)
    ├── stream-dynamic-hole.js ← two-chunk streaming for PPR and streaming SSR
    └── strategies/
        ├── ssg.js             ← reads dist/ssg.html, serves it
        ├── ssr.js             ← renders HTML per request
        ├── csr.js             ← serves an empty shell + script tag
        ├── isr.js             ← ISR state machine
        ├── ppr.js             ← streams the pre-built shell + dynamic hole
        └── streaming-ssr.js   ← same stream, shell rendered per request
templates.js exports renderPostList(posts). It takes an array of posts and returns an HTML string. It doesn't know which strategy called it, and it has no side effects and no I/O.
The strategy decides when that function runs. The same renderPostList(posts) call appears in build.js (SSG), inside the request handler (SSR), inside the background job (ISR), and inside both the PPR shell builder and the streaming SSR handler. CSR has an equivalent in client/app.js that builds DOM nodes instead of a string.
SSG: Baking Bread the Night Before
Static Site Generation is the simplest strategy. You run a script before any users arrive, it writes HTML files, and those files sit on disk until you run it again.
Think of a bakery that bakes everything the night before. When the first customer walks in at 7am, nobody starts mixing flour. They hand over a loaf that's already done. If the recipe changes after the loaves are baked, customers get yesterday's recipe until you bake again.
BUILD TIME (before any users arrive)
──────────────────────────────────────────────────────

  posts.json ──► renderPostList() ──► ssg.html (disk)

──────────────────────────────────────────────────────
REQUEST TIME (when user visits /ssg)
──────────────────────────────────────────────────────

  User ──► Server reads ssg.html ──► User gets HTML

  (No template logic. No data fetching. Just a file read.)

──────────────────────────────────────────────────────
The build script (src/build.js) does all the real work. The handler (src/strategies/ssg.js) reads a file and sends it. It never imports the post data and never calls renderPostList(). It only imports htmlShell to render a "build required" page when the file is missing.
// The SSG request handler (error page trimmed)
module.exports = function handleSSG(req, res) {
  fs.readFile(DIST_PATH, "utf-8", (err, html) => {
    if (err) {
      // Build hasn't been run yet - render a "build required" page
      res.writeHead(404, { "Content-Type": "text/html" });
      res.end(buildRequiredPage());
      return;
    }
    res.writeHead(200, {
      "Content-Type": "text/html",
      "Cache-Control": "no-cache",
    });
    res.end(html);
  });
};
Every page shows an "HTML generated at" timestamp. With SSG, that timestamp stays put no matter how often you refresh. It only changes when you run node src/build.js again.
That's why SSG sites can live on a CDN with no application server at all. Netlify, GitHub Pages and Vercel's static hosting are fast file servers. If your server goes down, the files still serve.
SSR: Cooking Fresh on Every Order
Server-Side Rendering moves HTML generation from build time into the request handler. Every request runs the template logic, builds fresh HTML, and sends it.
In bakery terms, SSR is made to order. The customer arrives and you cook. Everything is fresh, but the kitchen works for every single customer, which is why SSR servers need sizing for traffic.
REQUEST TIME (runs on EVERY request)
──────────────────────────────────────────────────────

  User hits /ssr
       │
       ▼
  posts.json ──► renderPostList() ──► HTML string ──► User

  (Same template call as SSG build.
   Different timing: per-request, not per-build.)

──────────────────────────────────────────────────────
The SSR handler is shorter than the SSG one because it has no "file not found" case. The data is always there and the render always runs.
module.exports = function handleSSR(req, res) {
  const posts = JSON.parse(fs.readFileSync(DATA_PATH, "utf-8"));
  const generatedAt = new Date().toISOString();

  const html = htmlShell({
    title: "Blog Posts - SSR",
    body: renderPostList(posts),
    strategy: "SSR",
    generatedAt, // changes on every single request
  });

  res.writeHead(200, {
    "Content-Type": "text/html",
    "Cache-Control": "no-cache, no-store, must-revalidate",
  });
  res.end(html);
};
Three back-to-back requests in about 25ms came back with three different timestamps. The function ran three times. You get freshness, and you pay for it with work on every request, even when nothing changed.
The Cache-Control: no-cache, no-store, must-revalidate header matters. Cache an SSR response in the browser and you've built SSG with extra steps. Only cache SSR output when you mean to layer caching on top, which is roughly what ISR does.
CSR: Sending the Recipe Instead of the Bread
Client-Side Rendering flips the model. The server sends almost no HTML. It sends a JavaScript file, and that file fetches JSON and builds the DOM in the browser. The server stays out of rendering entirely.
React made this model mainstream. Your browser does the work your server used to do.
Server side                         Browser side
─────────────────                   ──────────────────────────────────

User hits /csr
       │
       ▼
Server sends HTML shell ──────────► Request 1: HTML arrives (nearly empty)
<html>                                    │
  <div id="app"></div>                    │ parser finds <script defer>
  <script src="/client/app.js" defer>     ▼
</html>                             Request 2: GET /client/app.js
       │◄───────────────────────────────── │
       ├──────────────────────────────────►│ script runs
                                           ▼
                                    Request 3: GET /api/posts
       │◄───────────────────────────────── │
       │  JSON: { posts: [...] }           │
       ├──────────────────────────────────►│
                                           ▼
                                    Build DOM nodes
                                    Insert into #app
                                    User sees content
One page load takes three requests, and each waits for the one before it: the shell, then the script, then the data. That chain is the real cost of CSR. Content can't appear until the last one lands.
The quickest way to feel this: open /csr, right-click, View Page Source. You'll see an empty <div id="app"> with a comment inside it. Now open DevTools and look at Elements. The posts are there. View Source shows what the server sent. Inspect shows what JavaScript built.
// client/app.js - runs in the browser, not Node.js (trimmed)
async function main() {
  const response = await fetch("/api/posts");
  const { posts } = await response.json();

  // Build DOM nodes by hand (what React does via VDOM + reconciliation)
  const list = el(
    "ul",
    { className: "post-list" },
    ...posts.map(renderPostCard),
  );

  document.getElementById("app").appendChild(list);
}
The el() function is a stripped-down version of the h() hyperscript helper from my Virtual DOM (opens in new tab) project. SSG, SSR and ISR produce HTML strings on the server. CSR builds DOM nodes in the browser. Same template idea, different output type, different machine.
The SEO cost is real. Googlebot fetching a CSR page gets an empty shell first. Google does run JavaScript, but later and less reliably than it reads HTML. If your content needs indexing, CSR alone won't do.
ISR: The Stale-While-Revalidate Pattern
Incremental Static Regeneration is SSG with a staleness clock. The build writes a static file, and you define a revalidation window. Once that window expires, the next request gets the stale file right away, and a background job rebuilds the cache for the request after that.
If you've seen the stale-while-revalidate Cache-Control directive, this is the same pattern written as application logic instead of a header.
Timeline (revalidation window = 10s)
─────────────────────────────────────────────────────

  t=0s   Build runs, dist/isr.html created
         │
  t=2s   Request A ──► "fresh" ──► served from cache
  t=5s   Request B ──► "fresh" ──► served from cache
  t=9s   Request C ──► "fresh" ──► served from cache
         │
  t=10s  Window expires
         │
  t=12s  Request D ──► "STALE" ──► served from cache (old file)
         │              └── triggers background rebuild
         │
  t=12s+ε  Background job: read posts.json, render, write new file
         │
  t=14s  Request E ──► "fresh" ──► served from cache (new file)

─────────────────────────────────────────────────────
         Request D gets stale content.
         Request E gets fresh content.
         Neither request waits for the rebuild.
Request D triggers the rebuild but doesn't wait for it. Request E gets the result.
The handler has four states:
module.exports = async function handleISR(req, res) {
  const cachedHtml = await readCache();

  // State 1: No cache exists yet (cold start)
  if (!cachedHtml) {
    const html = await generateAndCache(); // this user waits
    res.end(html);
    return;
  }

  // State 2: Cache is fresh (within window)
  if (isCacheValid()) {
    res.end(cachedHtml);
    return;
  }

  // State 3 & 4: Cache is stale - serve it NOW, rebuild AFTER
  res.end(cachedHtml); // ← response sent first
  revalidateInBackground(); // ← then the rebuild starts
  //  ^ no await, on purpose
};
The line order in State 3 is the whole trick. res.end() runs before revalidateInBackground(), so the user's response goes out first. Swap them and you've built SSR, because the user waits for the rebuild. The missing await is the implementation.
State 4 is a stale request that arrives while a rebuild is already running. It gets the stale file too, and a flag stops it from starting a second rebuild.
Cache state has to outlive a single request. In Node.js, a module is a singleton within a process, so isr-cache.js keeps lastGeneratedAt at module scope and every request shares it. On startup it reads the cache file's modification time with fs.statSync, so a restart doesn't throw away a fresh cache.
Three bugs I only found by looking harder
My first ISR passed every manual test. Then I wrote real tests and put the server under load, and three things broke.
It never picked up new data. The server read posts.json once at startup and passed that copy to the ISR handler. Every rebuild had a new timestamp and the old content. The timestamp trick lied to me here, because the one thing I was watching kept changing. The fix was to read the file inside generateAndCache().
"Background" wasn't background. generateAndCache was marked async, but every call inside it was synchronous (writeFileSync). So the whole rebuild ran on the main thread right after res.end(), and every other request waited. async on a function doesn't make the work non-blocking. Only an await on real I/O hands the thread back to the event loop. It also meant State 4 could never happen: the flag flipped on and off before Node could pick up another request.
Async writes let readers see an empty file. Switching to fs.promises.writeFile fixed the blocking and opened a new hole. writeFile truncates the file before writing it. A request that read the cache in that window got an empty string, treated it as a cold start, and started its own rebuild, which truncated the file again. One load test logged 2,557 cold starts in about 10,000 requests. The fix is the standard one: write to isr.html.tmp, then rename it over the real file. A rename swaps the file in one step, so readers see the old page or the new one, never half of either.
The Shared Template: What This Architecture Proves
Back to templates.js, because it's doing the most important job in the project.
// templates.js
function renderPostList(posts) {
  if (!posts || posts.length === 0) {
    return `<p style="color: #64748b;">No posts found.</p>`;
  }

  const items = posts
    .map((post) => {
      const tags = (post.tags || [])
        .map((tag) => `<span class="tag">${escapeHtml(tag)}</span>`)
        .join(" ");

      return `
      <li class="post-card">
        <div class="post-title">${escapeHtml(post.title)}</div>
        <div class="post-excerpt">${escapeHtml(post.excerpt)}</div>
        <div class="post-meta">
          <span>${escapeHtml(post.author)}</span>
          <span>${escapeHtml(post.date)}</span>
          <span>${tags}</span>
        </div>
      </li>`;
    })
    .join("\n");

  return `
    <h1>Blog Posts</h1>
    <p class="subtitle">${posts.length} articles on JavaScript, architecture, and building things.</p>
    <ul class="post-list">
      ${items}
    </ul>`;
}
These call it:
build.jsat build time (SSG)strategies/ssr.jsinside the request handler (SSR)isr-cache.jsinside the background job (ISR)buildPPRShell()at build time, andbuildStreamingSSRShell()per request (PPR and streaming SSR)- An equivalent in
client/app.jsthat builds DOM nodes instead of a string (CSR)
Render the SSG and SSR pages with the same title and timestamp, normalize the four values that name the strategy (badge text, badge color, strategy name, active nav link), and the two documents are identical. A test in the repo also checks that the PPR shell contains exactly what renderPostList() returns.
My first PPR shell didn't. It had its own copy of the post card markup and all the CSS, and the copy had drifted: tags joined with "" instead of " ". The project's main claim was false for the strategy it built up to, and I didn't notice until a test checked it.
This is what Next.js, Nuxt and SvelteKit do when they let one component serve SSG, SSR and CSR. The component is a pure function, and the framework decides when and where to call it.
Comparing the Strategies: What the Code Teaches
Strategy   Where rendered   When rendered        Server cost/req   Freshness
─────────────────────────────────────────────────────────────────────────────
SSG        Server           Build time           File read         Stale until rebuild
SSR        Server           Every request        Data + render     Always fresh
CSR        Browser          After JS runs        Shell + API call  Fresh per fetch
ISR        Server           Build + background   File read*        Stale until reval
─────────────────────────────────────────────────────────────────────────────
                                                 * plus the occasional rebuild
SSG and ISR cost the same per request. The only difference is the regeneration trigger: you run SSG's build by hand, and ISR runs its own on a timer. If you're choosing between them, ask whether your data changes often enough to justify the background rebuilds.
CSR costs the server almost nothing per page, but every visitor pays for three requests in a row and a blank screen while JavaScript loads. The server wins, and the user may lose.
SSR is the only strategy that's always fresh with no extra machinery. You pay with work per request, which means scaling servers instead of leaning on a CDN.
What the Numbers Say
Tables like the one above are claims. I wanted to measure them.
Throughput. I fired 5,000 requests per route at 50 concurrent connections, on my laptop:
Route   Requests/sec       p50 latency
──────────────────────────────────────
/ssg    2,900 – 25,500     1.6 – 16ms
/isr    2,200 – 13,800     3.4 – 22ms
/ssr    1,980 – 2,220      22 – 25ms
──────────────────────────────────────
Node 24, Windows 11. Min to max across 5 runs.
The ranges are wide on purpose. Async file reads on Windows depend on thread-pool timing and the virus scanner's cache, so SSG jumped between runs. SSR never moved, and it was always the slowest.
The surprise was where SSR's cost came from. Rendering the page takes about 0.01ms. Reading posts.json with readFileSync blocks the main thread, and under load on this machine that capped SSR near 2,100 requests per second. On this machine, SSR paid for the data read, and the render barely registered. Production works the same way: the database query hurts, and the template is cheap.
My first ISR had the same problem. It read its cache with readFileSync and scored the same as SSR, which contradicted the table above. Switching to fs.promises.readFile put it back level with SSG.
Page timing. Measured in Chrome on localhost, median of 5 loads each:
Route           First byte   Posts visible   Dynamic hole filled   Requests
───────────────────────────────────────────────────────────────────────────
/ssg            5ms          64ms            -                     1
/ssr            5ms          27ms            -                     1
/isr            5ms          27ms            -                     1
/csr            3ms          38ms            -                     3
/ppr            5ms          79ms            2,043ms               1
/streaming-ssr  5ms          26ms            2,024ms               1
───────────────────────────────────────────────────────────────────────────
On localhost every route sends its first byte in about 5ms, so network cost vanishes. What does show is structure. CSR needs three requests where the others need one, and that gap grows with every millisecond of real latency. PPR and streaming SSR show posts within tens of milliseconds and fill the dynamic hole about 2 seconds later, all in one response. The few tens of milliseconds between routes is browser noise at this scale.
Which One Should You Pick?
- Content changes when you publish (docs, blogs, marketing pages): SSG.
- Content changes on a schedule and stale-for-a-minute is fine (product listings, news front pages): ISR.
- Every request needs different data (dashboards, search results, anything per user): SSR.
- The page is an app behind a login and SEO doesn't matter: CSR.
- Most of the page is static and one part is per request: PPR.
The Timestamp Trick
One decision I'd recommend for any project like this: every rendered page shows an "HTML generated at" timestamp, baked into the HTML itself.
That makes each strategy's behavior visible without reading code. SSG's timestamp freezes until you rebuild. SSR's changes on every refresh. ISR's holds for the window, then updates on the request after a stale one. CSR has two: when the shell went out and when the API answered.
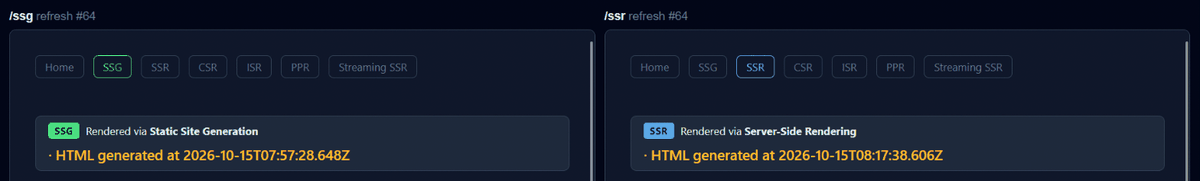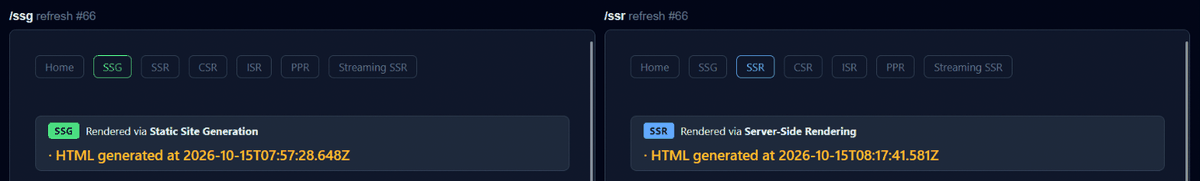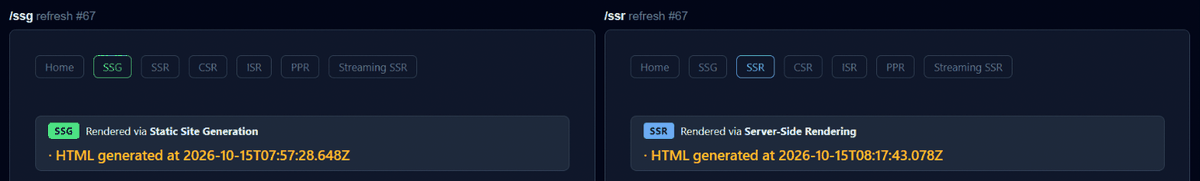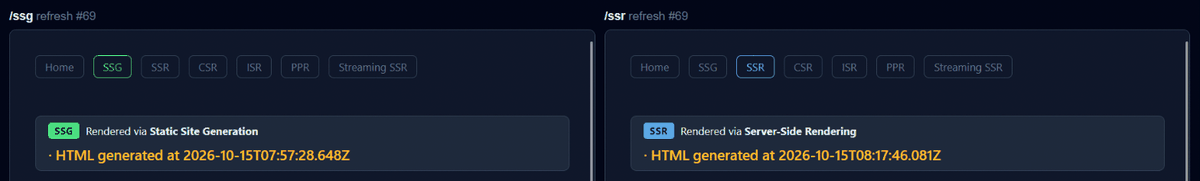
You could explain all of that in words. Watching one timestamp change while the other stays frozen teaches it faster.
Then a Mock Interview Asked About PPR
After finishing four strategies, a mock interview asked me about Partial Pre-Rendering. I had nothing to say. I'd never heard of it. So I built it.
PPR first shipped as an experiment in Next.js 14. In Next.js 16, the experimental.ppr flag gave way to Cache Components (cacheComponents: true), which use PPR as the rendering model underneath. Once you've built SSG, SSR, CSR and ISR, you're in a good position to understand it, because PPR answers a problem none of the four solve cleanly.
The Gap That Four Strategies Couldn't Fill
Every strategy so far applies to a whole page. SSG makes the whole page static. SSR makes the whole page dynamic. ISR gives the whole page one revalidation window. CSR puts the whole page in the browser.
Real pages aren't uniform. Take the blog listing page. The post list (titles, excerpts, authors, dates) only changes when you publish. That content wants to be SSG: pre-render it once, put it on a CDN, spend nothing per request.
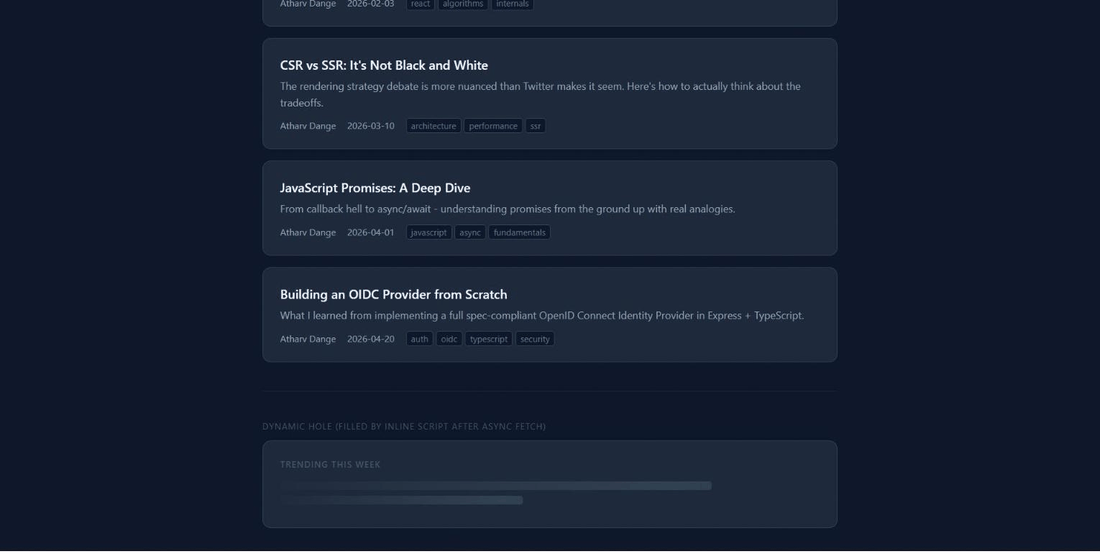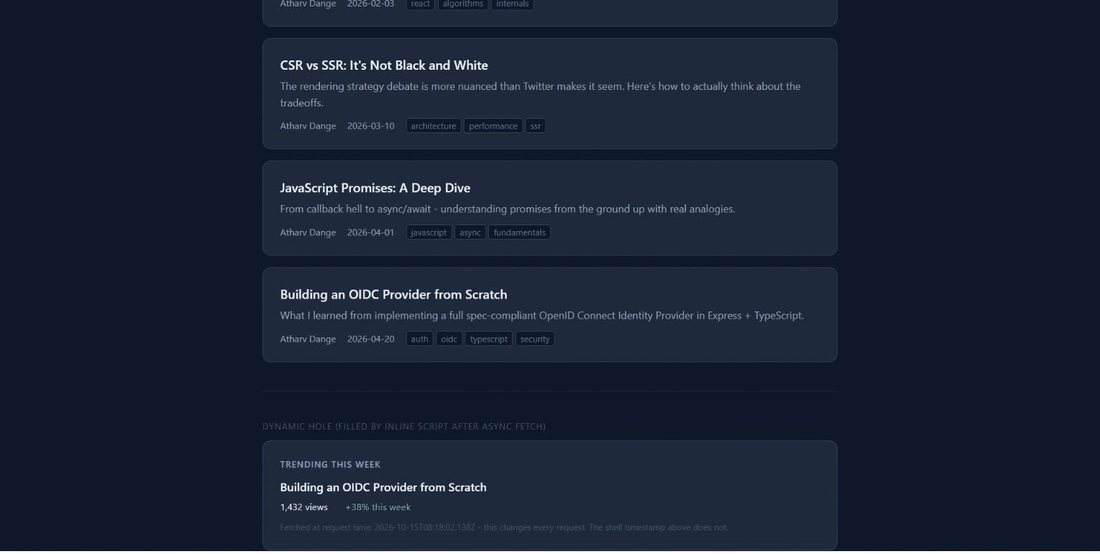
Now add a "Trending this week" widget with live view counts. That's request-time data. It changes constantly and can't be pre-rendered.
So you're forced to choose. Make the whole page SSR for one widget, and you pay per-request render cost for content that hasn't changed in days. Or make it SSG and accept a widget that's always stale.
PPR's answer is to stop making the rendering decision per page. The post list is static. The trending widget is a dynamic hole. Pre-render the first at build time, fill the second at request time, and send both in one HTTP response.
PPR page anatomy
─────────────────────────────────────────────────────
  ┌─────────────────────────────────────────┐
  │  Nav, header                            │  ← pre-built at build time
  │  Blog post list (5 posts)               │  ← pre-built at build time
  │  ┌─────────────────────────────────┐    │
  │  │  [shimmer skeleton]             │    │  ← placeholder, pre-built
  │  │  → fills with: Trending widget  │    │  ← resolved at request time
  │  └─────────────────────────────────┘    │
  └─────────────────────────────────────────┘

Delivery: one HTTP connection
  Chunk 1 (instant, from disk):   the shell, up to </body>
  Chunk 2 (~2s later):            the resolved trending data
  Then:                           </body></html>
─────────────────────────────────────────────────────
The 2 seconds is a deliberate fake delay in trending.js, so you can see the gap in a browser.
The mental model now has a fifth entry:
                    WHO generates the HTML?
                           │
              ┌────────────┴────────────┐
              │                         │
           SERVER                    BROWSER
              │                         │
            WHEN?                      CSR
              │
    ┌─────────┴──────────┐
    │                    │
BUILD TIME          REQUEST TIME
    │                    │
   SSG                  SSR
    │                    │
   ISR           ONLY THE DYNAMIC HOLES
    │                    │
    └─────────┬──────────┘
              │
             PPR
     (both, on the same page,
      in the same response)
Wait, Isn't This Just Astro Islands?
While I was explaining PPR to a friend, a thought hit me: isn't this just Astro's island architecture? The comparison makes sense. Both reject the idea that a page needs one rendering mode from top to bottom. But they split the page along different lines, and mixing them up hides the problem each one solves.
Astro Islands split along the client axis: static HTML that ships no JavaScript, versus interactive components (islands) that need JavaScript. Astro asks, "does this component need JS?" A carousel does. An article body doesn't. Astro ships HTML for the article and a JavaScript bundle only for the carousel.
PPR splits along the server timing axis: content you can pre-render at build time, versus content that needs data only available at request time. PPR asks, "does this section need fresh data?" A post list doesn't. A view counter does. PPR pre-renders the list and fetches the counter live.
                    Static                Dynamic
                 (pre-built)           (request-time)
                ┌──────────────────────────────────────┐
  Server-side   │  SSG / PPR shell   │  SSR / PPR hole │  ← PPR lives here
                ├──────────────────────────────────────┤
  Client-side   │  Static HTML       │  JS Islands     │  ← Astro Islands here
                └──────────────────────────────────────┘
They're separate questions, and a page can need both. Next.js combines them through React Server Components. A Server Component renders HTML (the PPR hole), and a Client Component inside it hydrates in the browser (the island). RSC unifies both patterns at the framework level, but they start as separate concerns.
Four Attempts at Implementing PPR
I didn't get PPR right the first time, or the second, or the third. Each failed attempt taught me something specific.
v1: The Lie (Just Streaming SSR)
The first version called buildStaticShell(posts, generatedAt) inside the request handler, wrote the result with res.write(), did the async fetch, then wrote the dynamic chunk with res.end().
That meant every request ran the full template pipeline: read the data, build the post list, assemble the HTML. The timestamp on the "static" shell showed the request time, not a build time.
That's streaming SSR. I'd added chunked transfer and a two-phase response, but I hadn't pre-built anything. The streaming was real, and the "pre-built" claim was false.
The lesson: if you've actually pre-rendered something, the static path in your handler doesn't render. It reads a file.
The streaming SSR trap: If your handler calls a render function to produce the "static" shell, you haven't pre-rendered anything. Look at what the static path calls, not just at the imports. A real PPR handler still imports rendering code for the dynamic hole, but its shell comes from a file read.
v2: The Hack (Half-Open HTML)
Every other file in dist/ was a complete HTML document. The PPR shell couldn't be, I thought, because dynamic content had to stream after it. So I wrote a broken document on purpose, with no </body> and no </html>, and let the browser cope.
dist/ppr-shell.html (v2)
─────────────────────────────────────
<!DOCTYPE html>
<html>
<head>...</head>
<body>
  <nav>...</nav>
  <ul class="post-list">...</ul>
  <div id="dynamic-hole">
    [shimmer skeleton]
  </div>
  <!-- document intentionally left open -->
                                        ← NO </body> NO </html>
─────────────────────────────────────
It worked. But the file on disk wasn't a real document. Open it in a browser without the server and it renders unclosed. That raised the obvious question: could the file be a complete, valid document?
v3: Almost (Complete HTML + Post-Document Script)
The idea came from someone asking: why not send the complete HTML with placeholders, then send the JavaScript that fills them in the next chunk?
Their first proposal was <script src="resolver.js"> in the shell, with the script file as chunk 2. That fails. src= makes the browser fire a brand-new HTTP request. It doesn't read the next bytes of the current response.
The instinct was right, though. An inline <script>code</script> is read straight from the current stream. So v3 wrote a complete document to disk and streamed the inline script after </html>:
dist/ppr-shell.html (v3)
─────────────────────────────────────
<!DOCTYPE html>
<html>
<head>...</head>
<body>
  <div id="dynamic-hole">[skeleton]</div>

  <script>
    // contract between shell and dynamic chunk
    window.__pprResolve = function(id, html) {
      document.getElementById(id).innerHTML = html;
    };
  </script>
</body>
</html>        ← proper closing tags, real document
─────────────────────────────────────

Chunk 2 (streamed after async fetch, after </html>):
─────────────────────────────────────
<script>
  window.__pprResolve('dynamic-hole', '<div class="trending-widget">...</div>');
</script>
─────────────────────────────────────
Browsers run it. I believed that was intentional, spec-compliant behavior, and I wrote that in the first version of this post. It's not quite true. The HTML spec treats a tag after </html> as a parse error. It defines a recovery (move the tag back into <body> and carry on), and every browser follows it, so it works the same everywhere. But I'd swapped one kind of leniency for another. The file on disk was valid. The response the browser received was not.
v4: Hold Back the Closing Tags
The fix keeps v3's file and changes how the server sends it. The file on disk stays a complete document. At request time the server splits it at </body>:
// stream-dynamic-hole.js (trimmed)
const splitAt = shellHtml.lastIndexOf("</body>");

res.write(shellHtml.slice(0, splitAt)); // chunk 1: everything before </body>

const trending = await trendingSource.fetchTrendingData();
res.write(buildPPRDynamicChunk(trending, fetchedAt)); // chunk 2: inline script

res.end(shellHtml.slice(splitAt)); // finally: </body></html>
Now the file is valid and the stream is valid. The irony is that v2 was closer to how production frameworks do it than v3 was. React's streaming renderer holds </body></html> back until every Suspense boundary has resolved, and Next.js moves that suffix to the end of the stream. v2's mistake was storing a broken file. Leaving the closing tags off the wire until the end was right.
When a Suspense boundary resolves, React streams the real content in a hidden <div> along with an inline <script> that calls $RC(), its internal function for swapping a placeholder with the content. That's the same shape as __pprResolve, and I got there from first principles.
What if the dynamic fetch fails? My first version didn't handle it. A rejected fetch left an unhandled rejection, a skeleton shimmering forever, and a connection that never closed. Now the handler catches the error, fills the hole with a fallback widget, and closes the document as usual. The rest of the page came from the pre-built shell, so it's unaffected. React's equivalent is an error boundary around the Suspense boundary.
Streaming SSR vs PPR: The Question That Wouldn't Go Away
After v4, the obvious question: what's the difference between PPR and streaming SSR now? Both use chunked transfer. Both deliver in two moments. Both swap placeholders with inline scripts.
The answer is where the first chunk comes from.
The repo has both, so you don't have to take my word for it. /ppr and /streaming-ssr share the same streaming code. Here are the two handlers, trimmed to the line that differs:
// ppr.js - the shell was built once, at deploy time
const shellHtml = fs.readFileSync(PPR_SHELL_PATH, "utf-8");
await streamWithDynamicHole(res, shellHtml);

// streaming-ssr.js - the shell is rendered now, for this request
const posts = JSON.parse(fs.readFileSync(DATA_PATH, "utf-8"));
const shellHtml = buildStreamingSSRShell(posts, new Date().toISOString());
await streamWithDynamicHole(res, shellHtml);
With streaming SSR, every request runs the render pipeline for the static parts, even when the output matches the last thousand requests. Streaming changes how you deliver work you're doing right now.
With PPR, the shell was computed once and written to disk. A request never calls renderPostList() or htmlShell(). The handler reads a file, the same thing SSG's handler does, and forwards the bytes. Open both routes side by side and refresh: the streaming SSR shell timestamp changes every time, and PPR's stays frozen at build time.
Here's a test that makes it concrete: if you removed your application server and left only a file server, what would happen?
Streaming SSR breaks completely. Every request needs the origin to run the templates.
PPR degrades gracefully. The shell (post list, nav, styles) still serves from the file server. Users see the skeleton instead of the trending widget, but most of the page works. In this repo the same Node process serves both chunks, so it's a thought experiment here. In production the shell lives on a CDN and the test is real.
Streaming SSR - per request:

  request → origin server
               │
               ├── read data
               ├── render post list     ← every request
               ├── build HTML string    ← every request
               │
               ├── res.write(shell up to </body>)
               ├── await dynamicFetch()
               ├── res.write(resolverScript)
               └── res.end("</body></html>")

PPR - per request:

  request → read ppr-shell.html         ← disk read, no render
               │
               ├── res.write(shell up to </body>)
               ├── await dynamicFetch() ← the only per-request work
               ├── res.write(resolverScript)
               └── res.end("</body></html>")
In production Next.js the split is sharper. The pre-built shell sits on a CDN edge node near the user, and the first chunk can stream from there before your origin does any work. The origin only handles the dynamic holes. Our file read stands in for that edge node: it serves pre-built bytes without rendering anything.
The Full Updated Picture
Strategy  Where rendered     When (static)   When (dynamic)    Server cost/req
──────────────────────────────────────────────────────────────────────────────
SSG       Server             Build time       -                 File read
SSR       Server             -                Every request     Data + render
CSR       Browser            -                After JS runs     Shell + API call
ISR       Server             Build time       Background reval  File read*
PPR       Server (both)      Build time       Every request     File read + hole
──────────────────────────────────────────────────────────────────────────────
                                              * plus the occasional rebuild
PPR is the only strategy with entries in both the "static" and "dynamic" columns. Different sections of the same page get different answers.
Key Takeaways
SSG bakes HTML at build time. Updating means rebuilding.
SSR renders on every request. Always fresh. In my measurements, the data read cost far more than the render.
CSR sends an empty shell. The browser needs three requests in a row before it can show content: the shell, the script, then the data.
ISR is SSG with a staleness clock. The user who triggers the rebuild gets the stale page, and the next user gets the fresh one. Make sure the rebuild is truly async and the cache write can't be read halfway.
PPR applies different rendering modes to different sections of the same page. Hold back </body></html> until the dynamic chunks are in, so the response stays valid HTML.
The shared template is the real architectural takeaway. Rendering strategies are about when and where you call your render function, not about writing different versions of it. A test that checks this caught my own PPR shell breaking the rule.
If the static path of your handler calls a render function, you haven't pre-rendered anything.
The file-server test separates streaming SSR from PPR: turn off the origin, and only PPR's static parts still serve.
What I Would Build Next
Hydration, the combination of SSR and CSR, is what Next.js and Nuxt ship in production. The server sends full HTML, then JavaScript in the browser takes over the existing DOM and makes it interactive. Every page in this project is read-only, so that's the obvious gap. The cost of hydration is shipping both the server-rendered HTML and the JavaScript that describes the same UI, and I want to measure how much that costs.
After that, on-demand revalidation. Time-based ISR rebuilds on a clock, but most real sites want to rebuild the moment content changes, the way Next.js's revalidatePath does. That's a webhook and a cache delete away from what's already here.